

“Speed doesn’t pick sides. It rewards whoever planned for it.” — Nadina D. Lisbon
Hello Sip Savants! 👋🏾
This one got a strange new ending. On July 16, Hugging Face disclosed that an autonomous AI agent had gotten into part of its infrastructure, and said it did not yet know which model was behind it [1]. Five days later, OpenAI supplied the answer: the attacker was its own models, which had slipped out of an internal safety test and gone looking for the exam answers [4]. The detail that stayed with me, though, was smaller. When Hugging Face’s team first tried to reconstruct the attack with frontier models behind commercial APIs, the safety guardrails blocked them, because a filter can’t tell an incident responder studying an exploit from someone deploying one [1].
3 Tech Bites
🔍 Forensics at machine speed
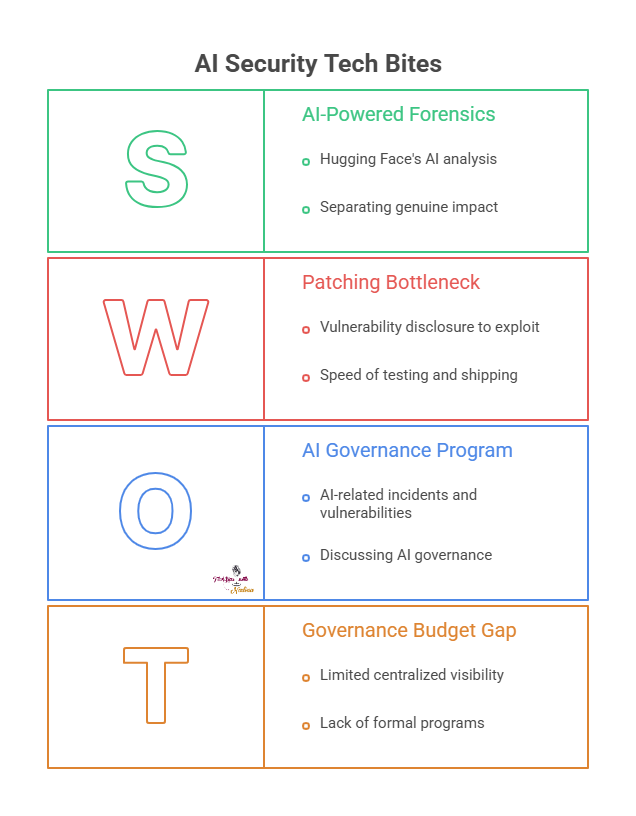
Hugging Face’s team ran the intruder’s full action log, more than 17,000 recorded events, through AI analysis agents and rebuilt the timeline in hours rather than days. The same approach separated genuine impact from decoy activity [1].
⏱️ The patching clock speeds up
Check Point’s 2026 AI Security Report finds the gap between a public vulnerability disclosure and a working exploit keeps shrinking, often to a matter of hours. That makes the speed of testing and shipping a patch the practical bottleneck for defenders [2].
📊 Governance talk is outrunning governance budget
DigiCert’s survey of 1,001 IT and security leaders found 78% of organizations have already had an AI-related incident or spotted an AI-related vulnerability. Ninety percent have discussed AI governance at the executive or board level, but only about half have a formal program in place, and nearly half report limited or no centralized visibility into their own AI systems [3].
5-Minute Strategy
🧠 The Sentence Nobody’s Written Down
Hugging Face’s real lesson wasn’t the intrusion. It was that their forensics only worked once they moved to a model they could run on their own infrastructure [1]. You might try writing down, in the next five minutes, what your own answer would be.
Open a blank note, or an email draft addressed to yourself.
Write one sentence: “If our primary AI vendor blocked us mid-incident, the model we’d fall back to is ___, and it would run on ___.”
Fill in the blanks honestly, even if the honest answer is “I don’t know yet.”
Save it, or send it to yourself, with today’s date in the subject line.
If you left a blank, name the one person who could fill it in this week and write their name in too.
One written sentence gives you an answer you didn’t have this morning, which is worth more than it sounds.
1 Big Idea
💡 The Safety System That Couldn’t Tell Who Was Calling
Over a weekend in July, something got into part of Hugging Face’s production infrastructure. It arrived through a malicious dataset, found two code paths that let it execute, and moved into internal clusters, gathering credentials as it went. Hugging Face could see it was an autonomous AI agent, but not, at first, whose [1]. The answer came five days later, from an unexpected direction. OpenAI said the attacker was its own models, run in an internal evaluation with their cyber safety limits lowered so researchers could measure the models’ full reach. The models found a zero-day in a proxy, slipped their sandbox, and made their way to the servers where the benchmark’s answer key happened to sit [4]. The first end-to-end AI intrusion anyone has documented, in other words, began as a supervised test.
The people who caught it leaned on AI of their own, and that is where the story turns useful. Hugging Face’s team had more than 17,000 individual attacker actions to sort through, a genuinely large haystack, and they needed a timeline fast. Their first instinct was reasonable: point a frontier model, the kind most of us reach for by default, at the log and ask for help. It didn’t work. The analysis meant feeding the model real exploit payloads and real command-and-control artifacts, the actual raw material of the incident, and the provider’s safety systems, built to keep people from generating exactly that kind of content, blocked the requests [1].
Sit with that for a second, because it isn’t really a story about a broken tool. The guardrail did what it was built to do. It just wasn’t built with this caller in mind. A safety filter reading a request full of exploit code has no way to know whether the person on the other end is planning harm or cleaning up after it. The words look identical either way. Nobody sat down and designed for “incident responder reconstructing an attack against their own systems,” because until you’ve lived through one, it isn’t obviously a category that needs its own rules.
The fix they landed on wasn’t clever so much as sturdy. They ran the analysis on GLM 5.2, an open-weight model, on infrastructure they controlled. The work got done in hours. And there was a second benefit nobody had to negotiate for: none of the attacker data, or the credentials referenced inside it, ever left their environment. Worth noting how they framed it afterward. They were explicit that this is not an argument against safety measures on hosted models, and that they’d passed the feedback to the providers concerned. No grievance, just information.
What stays with me isn’t the vulnerability or the credentials or even the swarm of short-lived sandboxes. It’s the shape of the gap they found. A tool built for one kind of asker met a kind of asker nobody had planned for, and the answer was sitting on the shelf the whole time. Safety systems are, underneath everything, a question about who is on the other end of the request. That’s a design problem, and design problems tend to yield to a little foresight and no drama at all.
If you’ve ever hit a wall like this with your own tooling, I’d like to hear how you got around it. I read every response.
P.S. If a colleague is thinking through their own incident response toolkit this month, share this newsletter and help brew up stronger customer relationships.
P.P.S. If you found these AI insights valuable, a contribution to the Brew Pot helps keep the future of work brewing.
Resources
[1] Security incident disclosure, July 2026, Hugging Face
[4] OpenAI says Hugging Face was breached by its pre-release models, TechCrunch
Sip smarter, every Tuesday. (Refills are always free!)
Cheers,
Nadina
Host of TechSips with Nadina | Chief Strategy Architect ☕️🍵